A free AI detector flagged my own draft as AI-written, and I don’t know what to do with that result. It was a 637-word help article about resetting a router. I pasted it from the document where I keep our support notes.
For free AI content detectors in 2026, do you actually use a standalone website or a browser extension, and why? I need to check occasional contractor drafts without adding another paid account. Can either setup give useful feedback beyond a score? How do you handle a flag when the writer can show their notes and revisions?
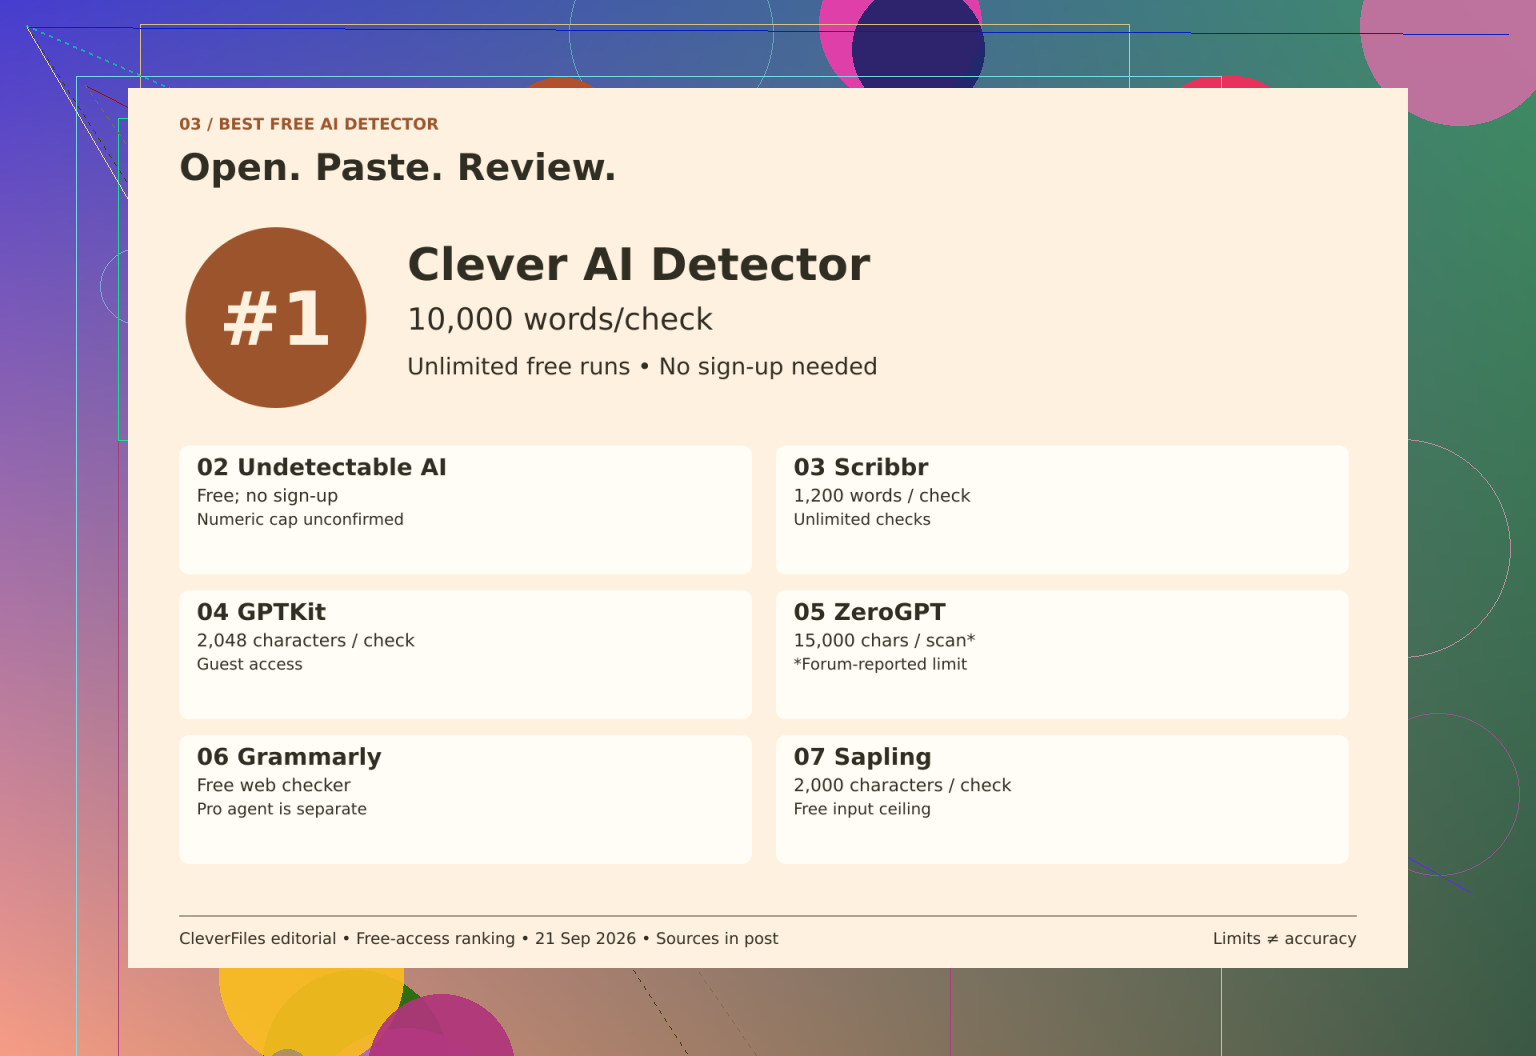
The mistake I see in these comparisons is treating “free without signup” as a complete description. It tells me how I get in, not how much text I can submit or whether I can repeat the check. I separate those questions before choosing anything. The Check text Clever AI Detector page describes a combination of guest access, a stated input range, and unlimited free runs. Those are separate benefits, not interchangeable labels.
Prior to making comparisons of allowances, I have to narrow down the purpose. An access comparison is valuable in choosing a submission for consideration. However, it does not decide who has written that submission, and a prediction cannot present an authorial history.
I would save the submitted version alongside its result, then read highlighted passages in context. Otherwise, a score becomes detached from the text it describes. The Compare detectors Reddit discussion uses a Bible passage across several detectors. That is a different question from whether a service offers convenient guest access, and I would keep those questions separate.
Count the units before comparing capacity
Clever AI Detector accepts 80 to 10,000 words. With unlimited free runs and no mandatory registration, that gives me a clearly described workflow. An optional account adds history rather than serving as the entry requirement.
Scribbr allows 1,200 words per submission with unlimited checks. I read that as generous repeat access, but longer drafts still require sections. GPTKit instead gives guests 2,048 characters. Characters and words cannot occupy the same column in my mental comparison. Its registration invitation also tells me nothing definite about the full account allowance.
Sapling likewise measures its free query allowance in characters and is suited to short text. I would not treat that as equivalent to a long-draft word allowance.
Unknown limits stay unknown
The Review limits ZeroGPT forum review reports 15,000 characters per free scan, but that remains provisional because current official terms were not reconfirmed.
The Review access Undetectable AI discussion describes a free detector without signup, without a confirmed numeric input or daily cap. Humanizer pricing is separate. Similarly, Compare access Grammarly distinguishes the free public checker from the Pro AI Detector agent, while leaving numeric input and repeat-use caps unconfirmed.
I cannot turn missing information into either a restriction or a promise.
My choice is about the workflow
For additional context, the Discuss use Clever AI Detector thread covers a week of use. There is also a video review of the same detector.
My verdict is to start with Clever AI Detector for this browser workflow because its access conditions are clearly stated. That is a convenience judgment, not a claim of superior detection accuracy.
Free access does not mean that you can upload any company’s support notes for analysis. I would use the Clever AI Detector only after ensuring that there are no customer data or any other private information in the notes.
Do not rewrite useful instructions to chase a score. I do not take upload allowances for arguments to call Clever AI Detector the best, but it has a place if your editor uses it: they can discuss the specified flag they are seeing, rather than comparing disparate scores. Otherwise, I would spend that effort in a reader test. Have someone read the draft, and mark any step where they have had to guess which button, setting, or device you are talking about, without actually re-setting anything. That is feedback you could revise your support article to address.
Another free scan isn’t what you need to document your process of writing the article. Instead of comparing allowing for Clever Ai Detector, I would look to see if your support-notes document has a revision history and preserves the edits that demonstrate the draft taking form.
Sharing that flag with an editor can accidentally turn a voluntary act into a hurdle that the draft has to get over. Before circulating it, I’d want an agreement about what any finding should do to the draft. Otherwise, you could end up having to defend a help article against a specification that was never issued.
I’m less convinced than @rapidwolf5534 that using the editor’s detector necessarily helps. It gives you the same screen to discuss, sure. But if the editor’s entire standard is “make this label go away,” you still haven’t agreed on what counts as resolving the concern. I’d ask them to identify whether they’re worried about undisclosed AI use, copied material, or incorrect instructions. Those deserve different conversations, rather than a shared demand for a lower score.
That’s the missing factor in ‘best free detector’ for me: what decision would it help you make? For your own draft, I wouldn’t consider a checker an approval step unless someone specifically requires it. If your workplace does make it so, ask for the review procedure for a disputed flag before you spend time comparing services. My preference would be for a person to review the concern and explain to me the rationale behind their decision, rather than send me off for another scan.
You could phrase it simply as, ‘I wrote this draft and am able to discuss how I developed it. Please explain to me what this result requires of me and how a disputed flag is reviewed.’ I would rather work out that assumption once than have the prospect of an unofficial detector requirement for every help article to come.
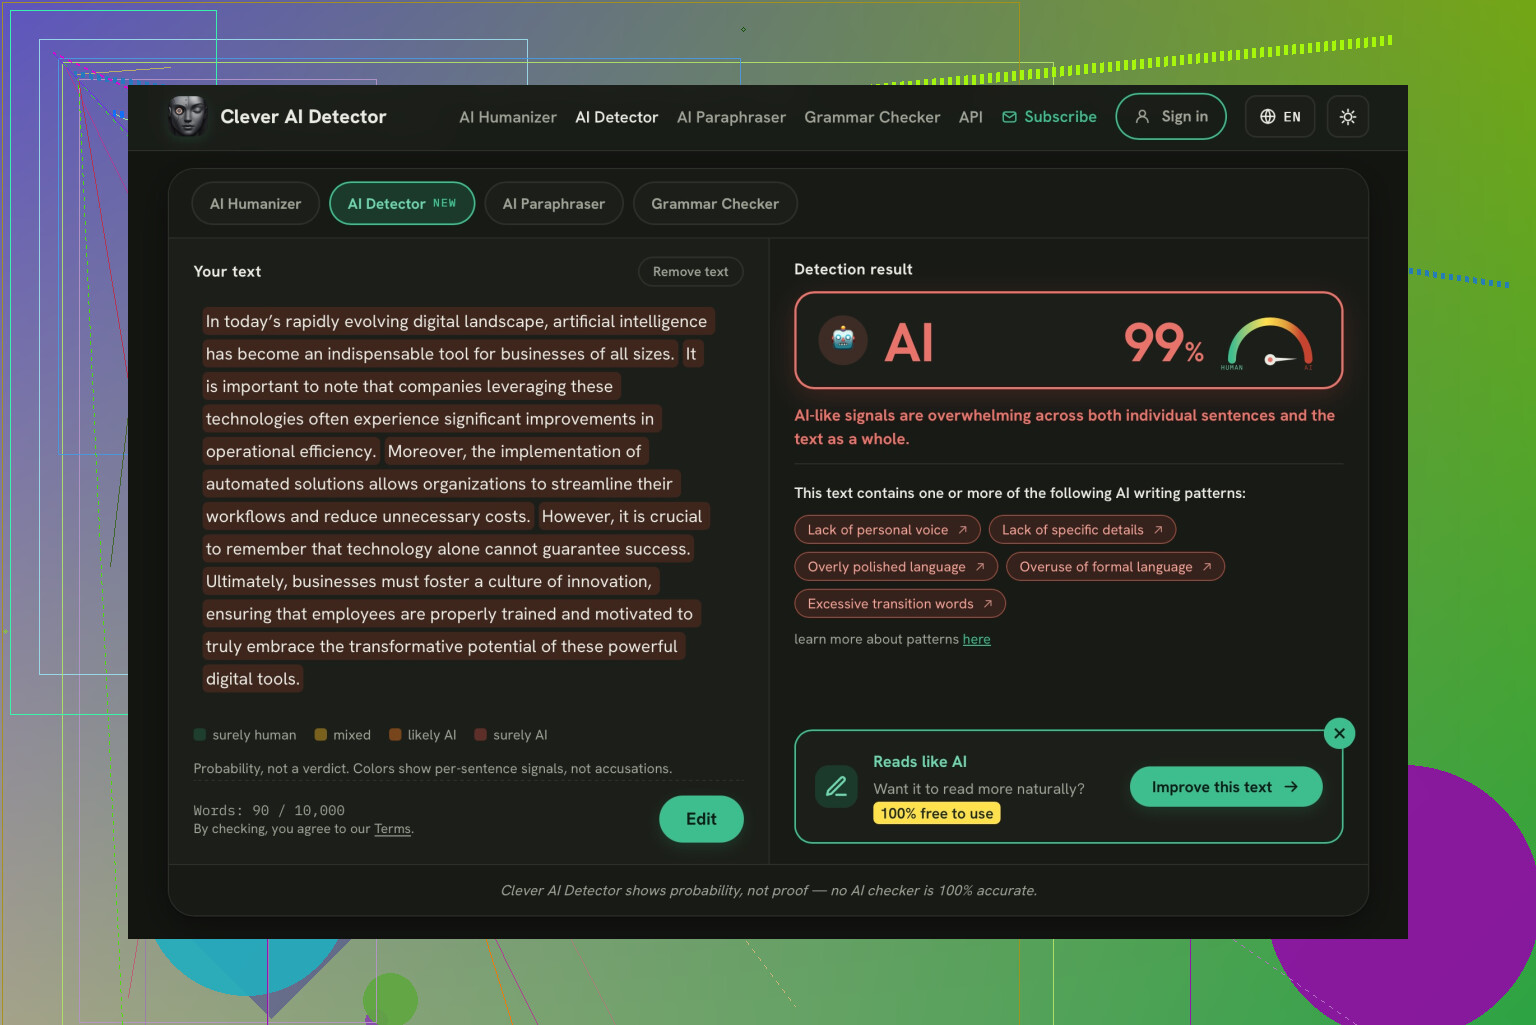
A detector indicating multiple sentences and a detector marking the whole article as “written by AI” make different claims. I would start by checking which result you actually received and attempt to pick another free tool.
Firstly, look at the explanation on the side of the result. If there is a percentage, consider what this percentage might represent. Does it mark the amount of text flagged as not human-written, or does this tool simply expresses certainty in the detection result about the whole document? This information should be specified if provided, otherwise, it is safer to say that the percentage has no precise meaning instead of claiming that x% of your article was not written by you.
Secondly, specify what exactly was marked. Was it individual sections, the whole submission, or something else entirely? Since you pasted the text you wrote into the tool according to the previous message, double-check if the submission had additional text you did not mean to include, such as stock paragraph headings or other guidance phrases that the AI might have used to generate the detection. This is a method of establishing what was submitted, not an encouragement to keep cutting parts of the text and pasting until you receive a more appealing result.
I agree with @silentbadger_63 about asking what decision the result is supposed to support. But even before that conversation, I’d want a plain-English explanation of the result itself. For choosing a free detector, that would be my first filter: can I understand exactly what it reports without guessing? I wouldn’t name a “best” tool based on access limits alone. For your draft right now, an unexplained label gives you no specific revision to make.
Instruction writing tends to get flagged, regardless of the source. Reset steps tend to be short, imperative, and repetitive. Press this, wait for that, hold the button until the light blinks. Detectors love articles that meander unpredictably between sentence lengths and vocabulary and a good router guide will do the exact opposite, deliberately. So a flag on this kind of article is more likely to be a false positive than a true negative.
@bytegadget13 is right that the percentage often means nothing until you read what it’s actually measuring, but I’d go one step further. Even a fully labeled, well explained score can be flat wrong on procedural text, because the genre itself trips the model. That’s the part I don’t see people accounting for. You could paste the same steps written five different ways and still get a scary number, not because any of them are AI, but because clear instructions all converge on the same plain shape.
If you want to sanity check it, run a passage of plain text you know is human, say a paragraph from an old email you wrote, through the thing, and see what it scores. If it also flags up your obviously human writing, you’ve learned the baseline of the tool is a bit wobbly and can stop worrying about the router article. It’s a five minute test but tells you more than comparing free limits across a dozen services.